
用于 Bangumi Wiki 的脚本合集。依赖官方 Archive 数据。
基于 DuckDB 的命令行/Web 筛选工具,支持 YAML 配置、交互模式、Web 界面。
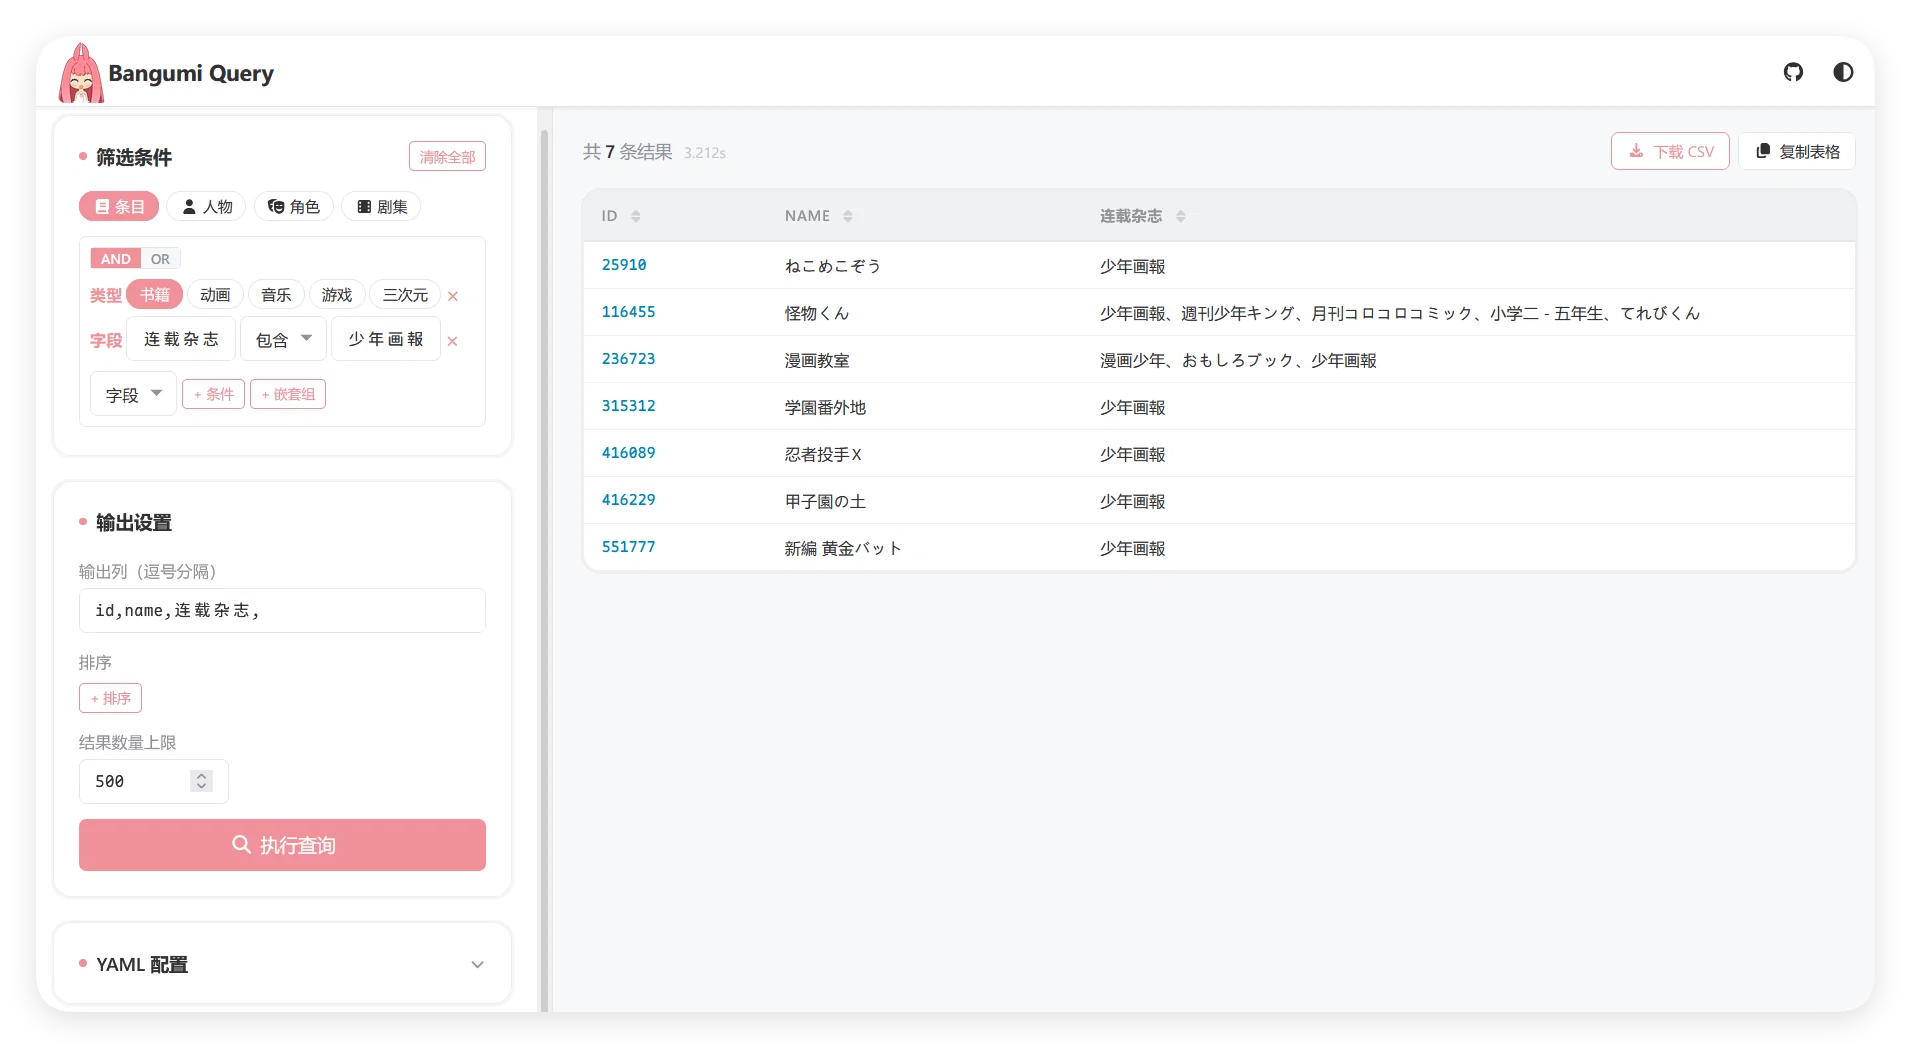


文档 · Bangumi 讨论
导出的 CSV 可用于 wikiBatch。
用户脚本,在 https://next.bgm.tv 上批量审核编辑条目/角色/人物的 Wiki 信息。
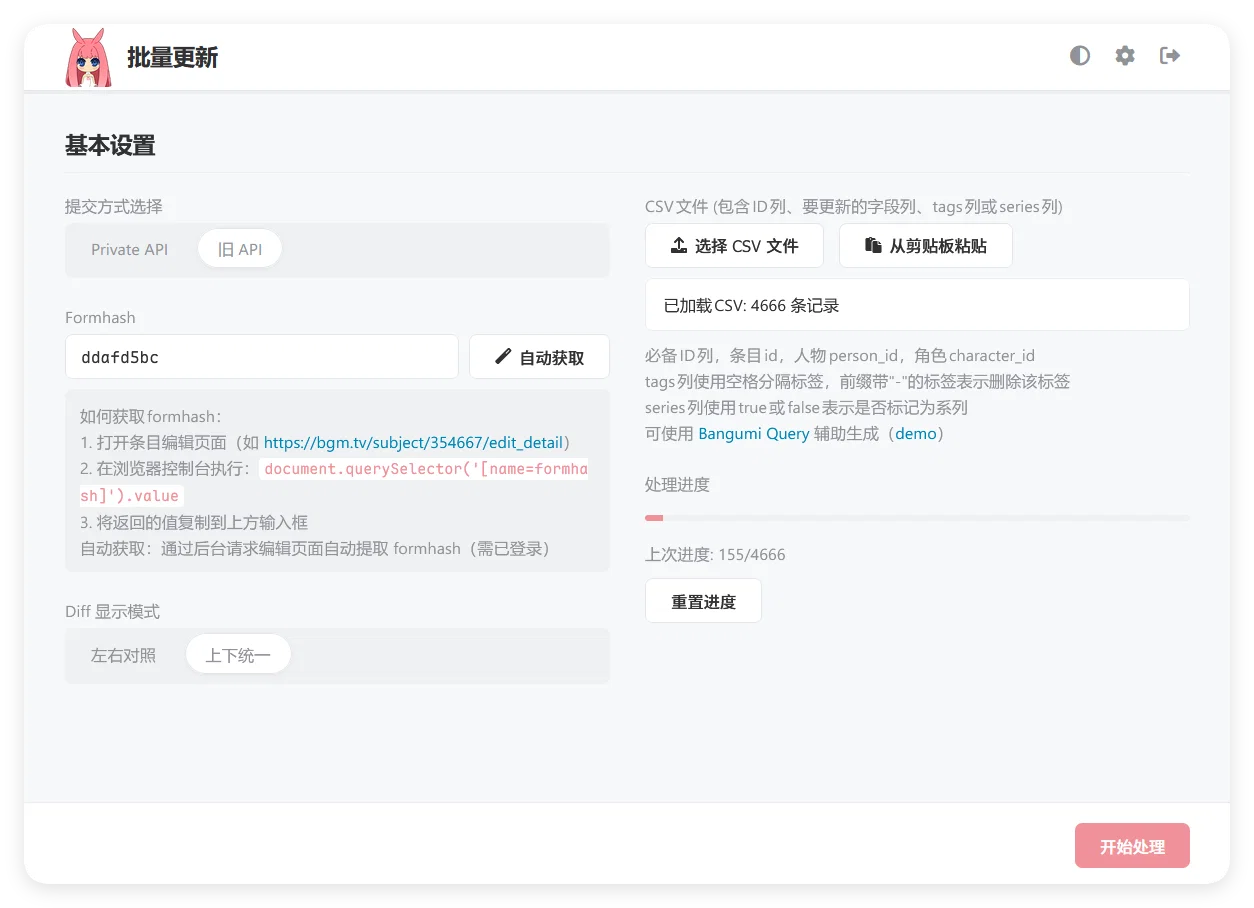
安装:https://raw.githubusercontent.com/inchei/bangumi-wiki-scripts/main/wikiBatch/dist/wikiBatch.user.js
用户脚本,将 person_alias.json.gz 导入 IndexedDB,提供 window.personAliasQuery / window.personAliasQueryAll 接口供其他脚本本地查询人物别名。
用户脚本,在条目页和人物关联页一键补完已填写但未关联的 STAFF。
或启用组件。
文档 · Bangumi 讨论
使用 uv 进行依赖管理,运行脚本使用 uv run script.py。
| 脚本 | 说明 |
|---|---|
| find_duplicate_isbns.py | 查找重复 ISBN 的条目(限 9784 开头的日本出版物) |
| person_alias.py | 生成人物别名 JSON 数据(一对多映射),供 bgq API 或 wikiPersonAlias 脚本使用 |
| check_volume_order.py | 检查单行本卷序一致性,输出 HTML 报告(uv run check_volume_order.py --archive-dir bangumi_archive --output report.html) |
| find_dup_person_name.py | 查找简体中文名同名人物,输出 CSV 供 sync_index.py 同步到目录 |
| extract_col.py | 从 CSV 列的 key:value 或 name(role) 中提取信息到新列 |
| find_missing_persons.py | 扫描动画条目 infobox 职位字段,找出出现 ≥2 次但未创建为人物的人员,生成 HTML 列表 |
根据 Archive 更新时间,每周三凌晨(UTC+8)通过 Github Action 自动运行,发布到 GitHub Pages(含筛选结果、缺失人物、卷序报告、人物别名 / 简中名数据文件下载)。
需要 CSV 文件用于 wikiBatch 批量编辑时,可本地运行:
mkdir -p results
for f in filters/*.yaml; do
  name=$(basename "$f" .yaml)
  ./bgq/bin/bgq query --config "$f" --data-dir bangumi_archive --format csv --output "results/${name}.csv"
donesync_index.py 可将 bgq 筛选结果同步到 Bangumi 目录,支持 subject/person/character/episode 四种类型。使用 next.bgm.tv 私有 API。
# 管道模式(类型自动从 CSV 列名推断:person_id→person, character_id→character, id→subject)
export =your_token
./bgq/bin/bgq query --config index_filters/example.yaml --data-dir bangumi_archive --format csv \
  | python sync_index.py --index 12345

# 文件模式
python sync_index.py --index 12345 --csv results/some-filter.csv

# 预览(不执行)
python sync_index.py --index 12345 --csv results/some-filter.csv --dry-run描述规则:
- 存在
index_desc列 → 用其值作为条目描述 - 否则 → 非 ID 列以
列名:值拼接(排除id、*_id和order列)
目录排序:
- CSV 含
order列 → 目录条目按order值排序 - CSV 无
order列 → 不修改目录顺序(新增条目 order=0,已有条目保留原顺序) - index_filters 的 YAML 配置了
sort时,sync_indices.sh会给 CSV 末尾追加order列(行序号 1,2,3…);无sort则不输出order列 - 同名人物同步(
find_dup_person_name.py的 CSV 自带order列):同一 order 值的同名组若全部已在目录且顺序一致,则整组保留原顺序,不会因组序号移位而整体重排
目录过滤器:index_filters/ 目录下的 YAML 需包含 target_index 和 target 字段。可 fork 本仓库,设置 BANGUMI_TOKEN secret,设置 test_sync_indices.yml 的 cron,并删除其他 .yml 文件,开启并使用 GitHub Actions 同步自己的目录。